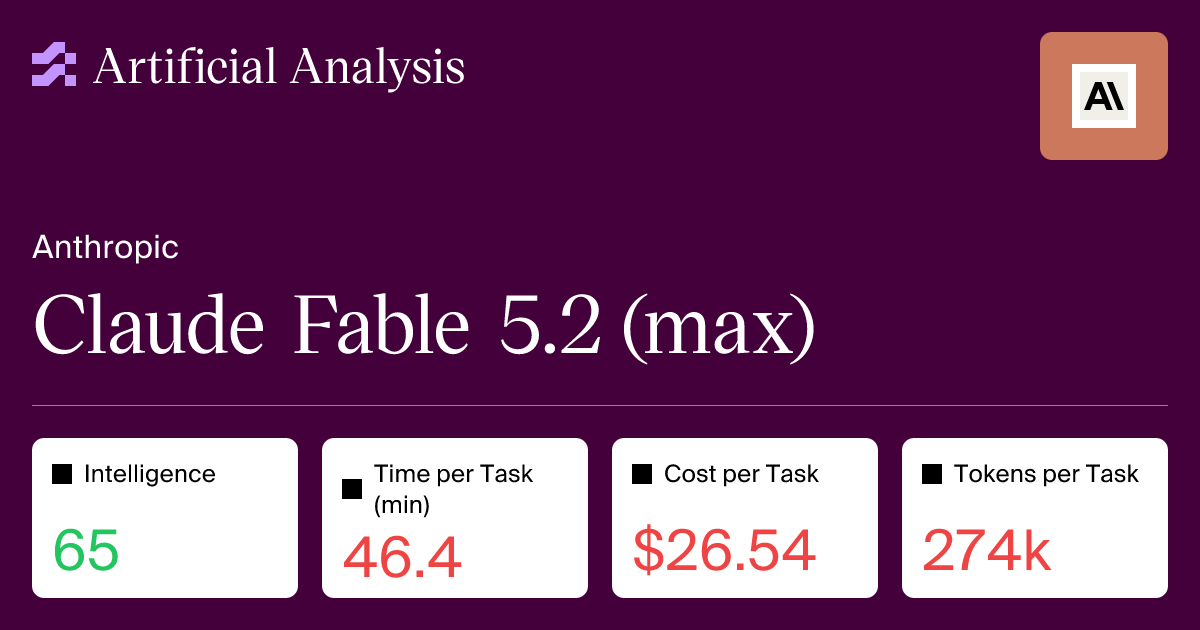
Claude Fable 5.2 (Max, Default Fallback) is amongst the leading models in intelligence, but particularly expensive when comparing to other models of similar price. It's also notably slow per task and very verbose. The model supports text and image input, outputs text, and has a 1M tokens context window.
Claude Fable 5.2 (Max, Default Fallback) scores 65 on the Artificial Analysis Intelligence Index, placing it well above average among comparable models (median: 40). When evaluating the Intelligence Index, it generated 275M tokens, which is very verbose in comparison to the median of 72.8M.
Pricing for Claude Fable 5.2 (Max, Default Fallback) is $8.00 per 1M input tokens (expensive, median: $2.00) and $40.00 per 1M output tokens (expensive, median: $10.00). On average, it costs $26.54 per task to evaluate Claude Fable 5.2 (Max, Default Fallback) on the Intelligence Index.
At 44.6 minutes per Intelligence Index task, Claude Fable 5.2 (Max, Default Fallback) is notably slow compared with the median of 12.7 minutes for comparable models (lower is better).
This page shows the reasoning version of this model.
Metrics are compared against models of the same class:
Artificial Analysis Intelligence Index v5.0.1 includes: AA-Briefcase v1.1, AutomationBench-AA, Terminal-Bench 4.0, FrontierCode 2.0, AA-Omniscience v1.1, GDP.pdf, HLE-Diamond, CritPt v2 (Hard Subset), Terminal-Bench-Science 0.1 . See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
Indicates whether the model weights are available. Models are labelled as 'Commercial Use Restricted' if commercial use is limited by conditions, and as 'Non-commercial' if the license prohibits commercial use.
Weighted average cost per Intelligence Index task. Each evaluation’s cost is calculated from input, cache hit, cache write, reasoning, and answer token prices, divided by task count, and weighted by its Intelligence Index weight.
Measures the performance of models on specific capabilities and industries
Agentic scientific research workflows in a terminal
Agentic software engineering in open-source repositories
Quantitative analysis on spreadsheets & documents
Legal agentic work, Hallucination-Gated All-Pass Rate
Product and brand videos designed in code, Elo
Truthful, acknowledges uncertainty, non-sycophantic
While model intelligence generally translates across use cases, specific evaluations may be more relevant for certain use cases.
AA-Briefcase Elo is a combined metric that aggregates analytical quality Elo, presentation Elo, and rubric pass rate, with rubric performance converted into Elo via synthetic head-to-head matches. Elo and 95% confidence interval bounds are clamped at 0.
AA-Omniscience v1.1 Net Score (higher is better) measures knowledge reliability and hallucination. It rewards correct answers, penalizes hallucinations, and has no penalty for refusing to answer. Scores range from -100 to 100, where 0 means as many correct as incorrect answers, and negative scores mean more incorrect than correct.
The number of tokens required per Intelligence Index task. This is calculated by multiplying the output tokens per eval by the relative weights of each benchmark in the Intelligence Index, then dividing by task count (excluding repeats).
The cost to run the evaluations in the Artificial Analysis Intelligence Index, calculated using the model's input, cache hit, cache write, reasoning, and answer token prices and the number of tokens used across evaluations (excluding repeats).
Price per token for cached prompts (previously processed), typically offering a significant discount compared to regular input price, represented as USD per million tokens. The values shown here are the cache hit price; cache write and cache storage are billed separately and vary by provider — see "Cache pricing by provider" for detail.
Larger context windows are relevant to RAG (Retrieval Augmented Generation) LLM workflows which typically involve reasoning and information retrieval of large amounts of data.
Maximum number of combined input & output tokens. Output tokens commonly have a significantly lower limit (varied by model).
Measured by time per task (minutes), output speed (tokens per second), time to first answer token and time to first token (seconds)
The weighted average time (minutes) per Artificial Analysis Intelligence Index task: output tokens per task divided by output speed, weighted by each benchmark's weight in the Intelligence Index.
Speed and latency metrics average each endpoint's runs over the past 5 days, and the error rate pools them. We run the benchmark every 6 hours, and endpoints of deprecated models every 18 hours.
Output tokens, including reasoning tokens, received per second over a request's full duration, from sending the request to receiving the final token. The headline value averages each Performance v3 workload over the past 5 days, then averages the workloads.
Time to first answer token received, in seconds, after API request sent. For reasoning models, this includes the 'thinking' time of the model before providing an answer. For models which do not support streaming, this represents time to receive the completion.
Common questions about Claude Fable 5.2 (Max, Default Fallback)
Claude Fable 5.2 (Max, Default Fallback) was released on November 9, 2026.
Claude Fable 5.2 (Max, Default Fallback) was created by Anthropic.
Claude Fable 5.2 (Max, Default Fallback) takes 44.6 minutes per Intelligence Index task (based on Anthropic's API), which is among the slowest compared to other models in a similar price tier (median: 12.7 minutes; lower is better).
Claude Fable 5.2 (Max, Default Fallback) has a time to first answer token of 221.21s (based on Anthropic's API), which is at the higher end compared to other models in a similar price tier (median: 12.25s).
Claude Fable 5.2 (Max, Default Fallback) costs $8.00 per 1M input tokens (at the higher end, median: $2.00) and $40.00 per 1M output tokens (at the higher end, median: $10.00), based on Anthropic's API.
When evaluated on the Intelligence Index, Claude Fable 5.2 (Max, Default Fallback) generated 275M output tokens, which is at the higher end compared to other models in a similar price tier (median: 72.8M).
Yes, Claude Fable 5.2 (Max, Default Fallback) is a reasoning model. It uses extended thinking or chain-of-thought reasoning to work through complex problems before providing an answer.
Claude Fable 5.2 (Max, Default Fallback) supports text and image input.
Claude Fable 5.2 (Max, Default Fallback) supports text output.
Yes, Claude Fable 5.2 (Max, Default Fallback) supports image input and can analyze, describe, and answer questions about images.
Loading comments…