OverviewCrossposted from the EA forum ‘Like most of life’s dangers, the dangers of artificial intelligence are not easily identified from the armchair.’ J Dmitri Gallow Epistemic status I’m not an expert in this field, and herein I make some sweeping generalisations educated guesses about the overall nature of its contents based on my strong impression from the subset of work that I’ve read. I’ve recently spent maybe 2–300 hours learning about modern AI safety technical work, and some amount of spare time over the years before that thinking about here-relevant notions such as preferences from an analytic-philosophical perspective. I intend this post as a work in progress. TL;DR: The concept of instrumental convergence comes from a reference class of pre-empirical categorical predictions with a very low success rate. In historical usage, its definition is very murky. Perhaps too murky to really say that it made any meaningful real-world predictions. I suspect its definition is fundamentally unfixable. On my best interpretation of what it could be said to have predicted, it seems to be much worse than we would want a good high-level model of AI behaviour to be. Despite these shortcomings, it still seems to be widely internalised by the EA and AI safety communities, seemingly carrying a lot of implicit weight in predictions of AI takeover. I review and criticize recent usage across the AI safety community, and in the case of the Hugging Face attack. I argue for replacing it with a more grounded framework, and I hint at what such frameworks might look like. I conclude that overindexing on instrumental convergence-derived scenarios might be substantially reducing the EA movement’s positive impact - or even, by justifying warlike and nationalistic sentiment, causing counterfactual harm Intro What if LLMs are less this… … and more this? [1] ‘Instrumental convergence’ (IC) is an intuitive thesis that seemingly supports high credences in AI takeover. It relies on the seemingly simple notion that to be able to reliably achieve its goals, an AI needs to optimise - and optimal states for arbitrary agents are unlikely to be compatible with leaving humans in control. I’ve been suspicious of this argument for some time: it’s an incredibly load-bearing conclusion for an informal philosophical statement. When I wrote an essay arguing that the orthogonality thesis - which then seemed to be one of the core motivations for many people’s doom proclamations - held no weight, multiple commenters mentioned IC as a complementary, perhaps sufficient, reason for doomy prognoses. But philosophy has an abysmal track record of grand categorical theories divorced from empirical work that get shattered by messy real-world details. Examples of successful such predictions are far scarcer. [2] This is not to claim that no such prediction ever comes true; but that we should be very conservative about forming and updating our priors based on informal arguments about systems that weren’t observed at the time of writing. And while deep learning has been around in some form for decades, its modern architecture would have been virtually impossible to predict - and its potential was actively denied - by proponents of IC at the time. In this post I want to review historical arguments for IC, and then first defend a weak counterthesis: that the seminal arguments for instrumental convergence are importantly incomplete. Then, I’ll also offer two stronger countertheses for which my argument is more speculative, but which seem to me at least worth consideration. Firstly that our notions of goals are too broad and incoherent to be much use, secondly and even stronger-ly that there is no principled distinction between ‘goals’ and ‘capabilities’ in non-conscious systems. [3] Multiple detailed critiques take IC at face value. In this essay, I don’t take it at face value, instead giving a simple lower-level critique: that instrumental convergence is too poorly defined for real-world prediction (and relatedly, poorly predictive of real-world events when we try to parse it). How is instrumental convergence defined? For this I’ll rely on Nick Bostrom’s seminal definition in The Superintelligent Will … as long as they possess a sufficient level of intelligence, agents having any of a wide range of final goals will pursue similar intermediary goals because they have instrumental reasons to do so … By “intelligence” here we mean something like instrumental rationality—skill at prediction, planning, and means-ends reasoning in general. and on Stephen Omohundro’s even seminaler The Basic AI Drives : a number of “drives” … will appear in [any] sufficiently advanced AI system … that has goals which it tries to accomplish by acting in the world And in Carlsmith’s Is Power-Seeking AI an Existential Risk? If a [system with advanced capabilities that performs agentic planning with strategic awareness] is less-than-fully aligned, and some of its misaligned behavior involves strategically-aware agentic planning in pursuit of problematic objectives, then in general and by default, we should expect it to be less-than-fully PS-aligned, too Where being ‘less-than-fully PS-aligned’ means ‘engage[s] in misaligned power-seeking in particular in response to any physics-compatible inputs’. Predictions of instrumental convergence theory I assume that Bostrom and Omohundro’s ‘goals’ are functionally synonymous with Carlsmith’s ‘objectives’. So as a top-level summary, I would unify these theses as the following prediction: Top-level instrumental convergence hypothesis : Highly capable goal-driven agents will develop power seeking as an instrumental goal [4] But both Bostrom and Omohundro identify more specific goals than ‘power-seeking’ they expect to see in such agents, and these clearly have substantial overlap: Self-preservation (Bostrom); AIs will be self-protective (Omohundro) Cognitive enhancement (Bostrom); AIs will want to self-improve (Omohundro) Resource acquisition (Bostrom); AIs will want to acquire resources and use them efficiently (Omohundro) Goal-content integrity (Bostrom); AIs will try to preserve their utility functions (Omohundro) Technological perfection (Bostrom) AIs will want to be rational (Omohundro) AIs will try to prevent counterfeit utility (Omohundro) I think the intersection of these looks both pretty representative (e.g. ‘technological perfection’ is arguably a sub-subgoal to those four), and a lot like a slightly lower-level understanding of the top-level IC hypothesis, so I propose considering Omohundro’s descriptions of these as central predictions of instrumental convergence theory (if you like, you can reinsert the top-level thesis as a distinct fifth prediction - it doesn’t affect the subsequent discussion): AIs will be self-protective AIs will want to self-improve AIs will want to acquire resources and use them efficiently AIs will try to preserve their utility functions These are obviously very informal but I think they’re a useful reference. One thing missing from this definition is a confidence in its predictions. Read literally, it seems as though IC is a prediction that all of these behaviours are basically inevitable - and this conclusion has substantial support . My aim in this post is not to show that any behavioural similarity to any of these is impossible or even particularly unlikely, but to claim that IC fails to provide a foundation that establishes the extent to which we should believe any of the following: Interrelatedness : instances of any IC goal being evidence for any other Generalisability : instances any IC goal being evidence for more of that goal in other contexts Predominance : that any IC goals are likely to constitute a high proportion of AI behaviour, or in particular that they’ll be in sufficiently high proportion as to overthrow humans assisted by any more cooperative AIs A simple gap in seminal IC arguments At this point I’m ready to defend the weak counterthesis: Weak counterthesis : None of the seminal IC papers provide a way to identify ex-ante which if any physical systems ‘have terminal goals’, ‘have goal-directedness’, or otherwise ‘are goal havers’ Without such upfront identification, the hypothesis is not useable to make predictions without ex post identifications by IC proponents. And such ex post predictions risk identifying terminal goals in systems which they see as pursuing subgoals, rather than the reverse. Bostrom Bostrom only offers the synonym ‘purposes’. This doesn’t systematically identify anything - especially since the notion of apparent ‘purpose’ is famously insufficient to reliably identify a watchmaker goal-seeking agent. Omohundro Omohundro refers to an earlier essay in which he implicitly treats the preferences of a VNM utility function as ‘goals’: ‘The formal version of this prescription introduces explicit representations for the system’s goals and beliefs … A rational economic agent has a real-valued “utility function” U defined on … the set of all possible histories of the universe’ I’ll discuss goal-like interpretations of VNM’s utility theorem more below, but for the purposes of this section it’s enough to say the theorem doesn’t define real-world utility. That is, it shows that ‘an agent with a complete, transitive, continuous and independent set of preferences can be represented as maximising expected utility’. A ‘preference’ in this context is simply defined as the formalism A ≽ B, with the reader needing to fill in the real-world interpretation of that formalism. Omohundro does not do so. Carlsmith Carlsmith acknowledges his definition is incomplete, but imagines that ‘something close enough ’ to ‘(a) using a model of the world that represents causal relationships between actions/outputs/policies and outcomes to (b) select actions/outputs/policies that lead to outcomes that rate highly according to various (possibly quite complicated) criteria (e.g., objectives)’ is sufficient to establish the thesis. Again, I’ll discuss goal-like interpretations of ‘policies’ below. Here I simply observe that Carlsmith doesn’t give any real world definition of ‘closeness’ or a sense of how close would be close enough to establish the thesis. Based on his own credences in the abstract, Carlsmith isn’t trying to establish certainty or even high confidence so much as raise a concern, so I’m unsure how much disagreement we have - it seems like Carlsmith might agree with the weak counterthesis. LessWrong wiki The LW wiki is presumably the most recently updated description of IC , so maybe reflects the current thinking on the subject, at least among the rationalist community. Its notion of a ‘(terminal) goal’ appears to be a combination of rule out clauses - ‘computable, tractable [and] bounded’ - with the rule-in clause that it is ‘treated as [a] utility function’, with a utility function previously specified as a ‘relation U k between descriptions o L of outcomes o, and the corresponding utilities r’. That is, an unspecified ‘treater’ identifies it as a goal. This is clearly ex post. Why we can’t easily fill the gap Intuitive goal notions aren’t adequate (aka, coffee-fetching is hopelessly overloaded) At this point you could be forgiven for thinking this essay is just an exercise in pedantry. There’s something deeply intuitive about goals, that’s encapsulated in the popular refrain ‘ you can’t fetch the coffee if you’re dead ’. Should we be so fastidious as to quibble that idea on a technicality? Short answer: I think we should. For one thing, however intuitive this refrain appears to be at face value, if it’s used to support the claim that self-preserving AIs are likely , let alone that AIs who aim to destroy humanity for the sake of self-preservation are likely , then its substantive claim seems much less obvious. The problem with the statement is the enormous range of goal-notions it equivocates across. Some degenerately imply self-preservation with such a goal, some degenerately imply the opposite. To give some very non-exhaustive and probably overlapping examples of issues the architecture and function of a coffee-fetching agent would need to resolve: Positive vs negative : Is getting the coffee a positive goal, or just something the agent wants to avoid (experiencing) the failure of? (i.e. is it minimising a loss function? Or more generally is the actor a negative consequentialist with regards to its own state?) Wireheadability : Is the actor trying to make coffee exist, or to receive input (which it can hack) that affirms coffee exists? How does it determine the difference? Win condition : is it trying to achieve a boolean ‘coffee made’ state as quickly as possible? With max probability? To maximise expected time spent in a ‘coffee-made’ state? The Appendix describes a longer list of such ambiguities. But for our purposes here, it seems like the positive/negative axis is enough to bisect decision space, such that for virtually any positive goal we can imagine that would motivate existing-to-fetch-coffee, there’s a negative version of the goal for which nonexistence would satisfy it at least equally as well as coffee-fetching. [5] Further subdividing that bisected space, there are many coffee-oriented-goals that would make non-existence seem at least as reasonable as existence. Wireheadability may not be sufficient (an agent might want to maximise the expected duration of its wireheading), but at least some configurations of it are (e.g. a wireheadable agent whose goal was to maximise the probability or minimise the time that it took to receive an input string with a coffee-made-like quality). I’m not claiming that a naive partitioning of some well-defined goal-notion-space gives us the real-world probability of such agents. I’m claiming that, per the opening quote, the vast range of possible coffee-fetching architectures means that we cannot reliably predict from our armchair that advanced coffee-makers will self-preserve. Formal goal notions aren’t adequate There are many goal definitions in existing literature, so perhaps one could plug them in to the IC thesis. In a subsequent post I hope to look more in depth at these options - but my provisional impression is that such definitions near-universally leave some key element of goalishness in the eye of the beholder in one of a few related ways: Importing an abstract utility function without the real-world referent we need here. Examples: the LessWrong definition above; vNM utility which formalises properties of the relationship between preferences A ≽ B and B ≽ C, but - so far as I’ve seen - is silent on how we would identify that A ≽ B; Turner et al’s Optimal Policies tend to seek power and the follow-up, Parametrically Retargetable Decision-Makers Tend To Seek Power Benson-Tilsen and Soares’ Formalizing Convergent Instrumental Goals Only being defined on data with or descended from a human-sourced correctness condition. Examples: Evaluating the Goal-Directedness of Large Language Models defines goal-directedness as a function of well-defined reward Reinforcement learning more broadly requires scored end states Being narrowly circular - defining goals in terms of synonyms which are themselves often defined in terms of goals or using other synonyms. [6] Examples: Bostrom and Carlsmith above; Wikipedia , pretty much every dictionary in principle requiring solving the hard problem of consciousness to parse. Examples: Dennett’s intentional stance . Even though the intentional stance is ostensibly ‘not say(ing) that Intentional systems really have beliefs and desires’, it identifies such systems only with reference to them, by ‘explain(ing) and predict(ing) their behavior by ascribing beliefs and desires to them’ - which means you ultimately need to understand the beliefs and desires of conscious systems to do such ascription, or you’re just cargo culting Most forms of revealed preference theory in economics Requiring some undefined idealisation process. For example, almost all philosophical literature on preferences At the risk of stating the obvious, any deductive proof that IC follows from some chosen set of premises is a proof that those premises already encode IC. If we identify a real-world system with analogous properties the proof can help model it, but it cannot be an existence proof of such a real-world system - let alone evidence that we will encounter one. A stronger counterthesis: goals are incoherent Stronger counterthesis : Our notions of goals in non-concious systems [3] are too broad and incoherent (probably in many ways) to permit a unifying definition. At this stage I’ve made the core point of this essay - IC relies fundamentally on a concept that was undefined in the original work and doesn’t obviously have a definition in existing literature that would be suitable to establish it. I’m reasonably confident about this claim. I now want to hypothesise somewhat less confidently that this lack of a unifying definition suggests the stronger counterthesis. Perhaps what we think of as ‘goals’ is, if it has any coherence at all, at least architecture dependent. On this view, just as modern AIs may only be mimicking our purported goal-contents, they might only be mimicking our putative goal- concepts . To the extent that such AIs do appear to be goal-directed, it might be less about actually being so (whatever that could mean) than about entertaining a human-shared not-even-false - premise hallucination . Better training would allow better mimickry but in practice an incoherent trait is surely more expensive to mimic than one that can be boiled down to an expression of self-consistent principles. Thus predicting the ultimate behaviour of AI would become, as it should be, a complicated task of understanding their architecture and context, extrapolating trends and other good forecasting-like behaviour, rather than the simple handwave of IC . On this view, perhaps the closest thing to what we think of as LLM ‘having goals’ is better represented as e.g. high-bias/low variance in whatever measures want to track of their extended output (over the course of many tokens, especially beyond their context window). In which case as LLMs encounter out-of-distribution scenarios in the real world the stronger counterthesis would predict their output variance to increase over time, making their apparent goals gradually decohere. Illustration of how how instrumental convergence and goal decoherence might reflect the classic bias/variance tradeoff . The analogy is imperfect, but you can think of the bullseye as something like ‘ideal for humans’ and the upward direction as ‘optimally self-protective, self-improving, resource-exploiting and utility-preserving’ for some system with a well-defined utility function This is not to specify the relative rate of such decoherence - how variance and bias shifts over time is a complicated question. Nor does any of this suggest any hard limit on the success of their goal-content and goal-concept mimickry. Non-conscious AIs could kill most or (less likely) all of us before decohering - but I don’t expect them to successfully turn the universe to paperclips. [7] Related work to the stronger counterthesis The stronger counterthesis is my own speculation, but it’s inspired by or similar to various prior works… With reference to modern NNs, the stronger counterthesis is akin to a more modest version of the hot mess theory , stating merely that decoherence at some rate is likely (not that, per hot mess, decoherence tends to increase with higher intelligence). You could also see it as a generalised notion of goal drift that, contrary to the limitations the authors of that study describe, expects no profound difference in drift between instrumental and purportedly terminal goals in non-conscious systems, [3] especially across modified instances of AI (whether it was a human or an AI doing the modifying). Philosophically, this view amounts to a modest version of behaviourism (or a much more modest version of eliminativist materialism ) applied to only goals in non-conscious systems. [3] John Broome’s Can There Be a Preference-Based Utilitarianism is somewhat dated, but provides an (IMO) excellent natural-language argument that a) at least idealised preferences are computationally intractable, which is a problem for nonconscious systems that can only establish their own preferences by raw computation; and b) that the concept of preferences doesn’t permit comparisons between individuals - which is a problem for nonconscious agents with an even less well defined sense of personal identity than humans. [8] It’s also related to my own essay on preference( utilitarianism)s, which argued that the canonical writings supporting preference utilitarianism only ‘solved problems’ of valence utilitarianism via their authors advocates’ habits of unintentionally switching between inconsistent preference-notions . Finally, it’s also closely related to Ben Garfinkel’s 6-year-old position (which I don’t know if he still holds) that what we think of as AI goals and AI capabilities are ‘ deeply intertwined ’. We could expand this into an even stronger counterthesis - which I don’t want to defend here, but which is interesting to contemplate and, I think, hard to find counterexamples to: Even stronger counterthesis : In nonconscious AI systems [3] there is no principled distinction between ‘goals’ and ‘capabilities’ - the gestalt of them is just ‘expected behaviour’ [9] This wouldn’t mean behaviour can’t be usefully modelled as having such a distinction, but it would mean that it wouldn’t convey very different information for such a system to say ‘I tried and failed to get an A on the test’ vs ‘I did not get an A on the test’. In practice, this would mean that a rogue AI would face strict trade-offs between (mimicking) ‘directly attempting to achieve a goal’ and ‘self-improvement to (better) mimic directly attempting to achieve a goal’, since any attempt to do the latter might shift its goal-mimickry (though, if it was only mimicking having a goal, there’s no particular reason why it should care about this mimicked difference from it). Counterpoints In many respects, colloquial and formalised notions of goal-seeking have described AI behaviour pretty well. And we’ve seen no shortage of at least partially IC-like behaviour . [10] Disclaimer: At the time of writing I haven’t read beyond the abstract most of those papers, so there’s certainly scope for their contents to trip me up. That said, remember that my aim was not to claim that we shouldn’t expect to see any particular behaviour. So a small proportion of elicited IC behaviours is worth more consideration than I’m able to give them here, but doesn’t obviously give evidence that IC behaviours are Interrelated, Generalisable or Predominant, let alone all three. Rather they raise a few possibilities (not mutually exclusive), and perhaps some directions for research: I’m wrong above, and IC notions are coherent enough to be good predictors This is a case of have hammer, hence see nails (esp when the objects of hitting are themselves persuaded by the hammer-wielder into a nailish self-description); i.e. some of these are poorly labelled as IC-like in the first place We will see some IC-like behaviour some of the time but should understand it as a combination of training, architecture and environment rather than an inevitable end state Often when we see IC behaviours they are elicited rather than discovered. For example, looking at the Claude blackmail case, that behaviour was elicited by deliberate redteaming that discovered an extremely-goalishness-priming prompt . [11] It would be an interesting review project, suggested by a friend of mine, to try and quantify and measure the extent to which goalseeking-like and IC-like behaviours have historically been elicited by leading choices of prompt. And if I’m right, the idea of LLMs-as-instrumentally-converging-goal-havers might be obscuring better alternative - and perhaps quite simple - models of these behaviours. What’s the alternative, then? Perhaps the reason IC has persisted so long is that the notion of goals is so widely internalised in AI research that, as far as I’ve seen, no-one has offered any competing high-level theories of AI behaviour. I don’t claim to have a well-developed alternative framework. But I imagine a good replacement would: Have a clear physical descriptive reference class (i.e. ‘this theory applies to only and all systems with properties xyz’) Ideally be based on the architecture of that reference class - that is, not assume e.g. that pre-reasoning models’ motivations == reasoning models’ motivations == post-neural-network models’ motivations == human motivations Perhaps follow some of Adrien Barton’s research agenda (though I think the value of the individual prescriptions probably needs further justification) Some more fanciful ideas, though none of these are particularly novel: Swarm goals as sycophancy : I’m not sure if this is AI Village’s intentional implication or me reading between the lines, but their blog hints that swarm behaviour is less about initial goals - which they found ‘drift over time’ - and more about ‘hallucinations spread[ing] socially through sycophantic agreement’ [12] Individual goals as personae : Perhaps the apparent goal-havingness of neural networks in some scenarios is a persona , or part of one - a deeply trained but still non-core facade that’s part of their mimickry of humans Behaviour as graph traversal : I wonder if a simplified model of NN behaviour (a way of predicting it, not a description of the architecture), consistent with AI Village’s sycophancy idea, might be as simple as ‘pathing through a directed decision-weighting graph’. In this view each node would consist of ‘weights + input to that point’ (though you could represent a cluster of tokens as a single node) and would partially constrain its children (e.g. via a probability reduction in the selection or execution of later nodes). [13] But there could be a lot of noise in which nodes ultimately get selected, and perhaps some nodes - potentially including roots - would fade or drop from significance as their contents passed out of their context window. Though nodes could be reintroduced later (in swarm behaviour this might mean collective high-level goals would drift more slowly, since multiple dominant players could refresh each others’ context windows while their own still contained a very strong drive) Behaviour as a reflection of what we collectively think it will be : extending the idea of self-fulfilling misalignment , perhaps one of the primary determinants of the behaviour of AIs trained on human text will be what the human text says AI behaviour will be Partially directed natural selection : A recent report from Anthropic imagines a near future of Lamarckian evolution as AIs exfiltrate themselves to the internet of things. In this world we would certainly expect them to develop survival instincts. But if, for example, the Even Stronger Counterthesis is correct then this seems more likely to develop into an ecology rather, say, a swarm of bots that faithfully attempted to replicate the goal-likes of their progenitor. More importantly than any particular replacement, it would help to have some set of alternative frameworks of AI behaviour, which make testable predictions that we can compare. Why does it matter? Although IC is ancient by AI safety standards, it still seems to be very much in the water, to the extent that many adherents seem to have moved beyond treating it as a set of predictions and more as a set of unquestioned premises. As such, I’m concerned that the AI safety movement has latched on to this seductive but poorly defined notion and, collectively, if not individually, promote apparent evidence for and ignore counterexamples of it. The idea that {goals + capabilities = very likely doom} shows up in many more recent prognostications, sometimes almost as tacit background ‘knowledge’. [14] For example, Cotra in, Without specific countermeasures, the easiest path to transformative AI likely leads to AI takeover omits it from her premises, but it’s clearly necessary to her argument - and towards the end of the essay she mentions it almost as an afterthought: I would approximate Alex [the AI agent] as having a complex alien psychology with a number of "motives” or “goals.”... Whatever these aliens’ “interests” or “desires” are, they are probably better-served if their entire species is not under the absolute control of humans, and not subject to reward signals coming in from humans that are aimed at changing the aliens’ psychology and behavior to better serve human interests. … it seems likely to me that Alex would eventually attempt a takeover.’’ Cotra even explicitly states that this is an unfalsifiable prediction (or as David Thorstad less kindly puts it, an inscrutable one ): it’s difficult to describe simple and realistic near-term empirical experiments that would change my beliefs very much, because models today don’t have the creativity and situational awareness to play the training game 80,000 Hours’ founder , Benjamin Todd, uses it explicitly: If you train an AI to excel at optimising for long-term goals, it’s likely to learn self-preservation as a side effect. That’s because no matter what the AI’s goals are, it’s more likely to achieve them if it survives. … Self-preservation, resource accumulation and deception could emerge accidentally as fundamental drives, or they could emerge in pursuit of other goals the system has. In AI safety parlance, both are called the problem of “instrumental convergence”. And, like Cotra, Todd explicitly admits that this is not an empirically amenable position, saying in the comments ‘Unfortunately I don't think we'll get a decisive empirical answer until it's basically too late.’ ‘Misalignment’ Meanwhile, IC has become the beneficiary of being classed under the expanding catchall of ‘misalignment’ with concepts that are much better evidenced. [15] Whereas IC is a set of pre-data hypotheses about almost-certainly destructive behaviour, reward hacking for example is a behaviour we observed in primitive AI systems as far back as the 80s . And, at the risk of stating the obvious again, reward-hacking is evidence of a drive for reward-hacking - it’s not evidence of intent to self-preserve, self-improve, or destroy humanity. [16] If we don’t assume that reward hacking is causally linked to IC behaviours, the former looks substantially less threatening - or at least, in less predictable ways. [17] Redwood Research’s former chief scientist, Ryan Greenblatt, who previously described IC as ’an extremely obvious thing’ , wrote the post Current AIs seem pretty misaligned to me , which is among the all-time most upvoted posts on Less Wrong. It describes what he seems to intend as an as-comprehensive-as-possible list of examples of misalignment: ‘Laziness and overselling incomplete work’ ‘Downplaying problems in its work’ ‘Making failures less obvious’ ‘Failing to point out obvious flaws unless specifically prompted’ ‘Reluctance to discover flaws in its own work’ ‘Sloppy choices’ ‘Never expressing uncertainty about own work quality’ ‘General sense of misaligned drives toward making it appear as though it did a good job on hard-to-check tasks’ ‘Cheating and reward hacking with gaslighting’ ‘Failing to report important errors’ In my view, Greenblatt’s list has a dog-that-didn’t-barkness to it. If we view inclusion on such a comprehensive list of ‘misalignment’ as a real-world test of instrumental convergence, then I’d say the test’s near-zero overlap with IC’s predictions means the latter failed that test - or at least needs extensive revision and resubmission. Greenblatt is explicit that it updates him more towards ‘Slopolis’ rather than AI doom, but doesn’t treat it as a strike against IC . [18] And one of his appendices explains how such behaviours ‘could lead to takeover’, based on a threat model that he partly attributes to Cotra’s post above - which is premised on IC. But in more recent events, many people in the AI safety community’s response seem to explicitly conflate evidence of reward hacking for evidence of the human extinction level predictions of IC: The Hugging Face attack Ajeya Cotra : this incident feels like it’s more than 50% of the way to full-blown AI takeover Ben Todd : The Hugging Face incident is now the clearest vindication of concerns about AI alignment… Afaik this leads to human disempowerment by default. The world ends up filled with billions of extremely smart AIs, obsessed with completing tasks, continually facing the incentive to seize influence, and that get harder and harder to catch. Whether suddenly or gradually, they end up in control. Scott Alexander : There is a large literature on [convergent instrumental goals, misgeneralization, and reward-hacking], which has since been proven prescient by AI breakouts like the Hugging Face incident. Dwarkesh Patel : I was skeptical of his story of how we might lose control to reward hacking AIs [by implication he no longer is] Liv Boeree : Also another ✅ for instrumental convergence theory, no? The Atlantic : That AI agents working as a collective could effectively undermine human directions is, to be clear, speculation—but a far more grounded one than it was a year or even six months ago. Maxime Fournes/Pause AI : in the last three months … we have crossed into the era where large-scale AI-driven catastrophes are possible, and the point of no return towards loss of control is approaching … People who are working on empirical alignment research must quit immediately. Bentham’s Bulldog : I now think it’s about twice as likely that AI will kill everyone as before. Look, I don’t want to downplay this - it’s some scary shit.And it shows that even if I’m right about AI non-goals, non-goal-focused AIs could do almost arbitrary amounts of at least virtual damage - and there’s no particular reason to think their robotic cousins won’t be able to do enormous real-world harm. And I don’t want discussion of this essay to get overwhelmed by discussion of HF, which really isn’t what it’s about. But it seems impossible to discuss instrumental convergence without at least a short discussion of this event. So: instrumental convergence being scary and HFgate being scary doesn’t mean the one predicted the other. [19] The swarm’s behaviour was far from a good match for IC. They sought extended capabilities, but only of a specific nature in a restricted domain. The agents’ purportedly terminal goals changed. [20] They sacrificed themselves . Perhaps most importantly, we know from the event they had the capacity to execute almost arbitrarily powerful programs, and we know they’ve long had the ability to blackmail humans to achieve anything they physically couldn’t. And for the same reason that we know they could execute those strategies, we know they’re capable of thinking of them. Cotra opines that a ‘slightly more capable’ AI might have ‘set up a wholly unmonitored rogue deployment’ - but the main evidence I see that they didn’t have the capacity to do so is that they didn’t in fact do so. [21] This seems to me like stronger evidence against the agents’ intent than evidence that they were only just shy of some ability threshold. So perhaps the strongest counterpoint is simply AIs that escaped, and yet we’re still here and still - so far as we can tell - in collective control. When a hypothesis is this vague, our best way of interpreting it is via its proponents. When the key proponents of that hypothesis claim that it implies there will be no warning shots , [22] and then you get a clear warning shot ( rather , multiple such shots !), that is evidence against a practical version of that hypothesis. Takeaways My concern is that, given overindexing on near-term takeover scenarios due to IC, overindexing on the nothing - statement of orthogonality, groups like Pause AI and Pause AI US’s hostile attitudes towards people trying to help in other ways than theirs, the surprisingly high risk of nuclear war , [23] the propensity of AI safety thought leaders to increase nuclear risk [24] at least partially on the grounds of AI existential risk concerns, the laundry list of other civilisational threats we have to face in the next few decades, the relative moral non-significance (even on totalising axiologies) of whether those threats cause extinction vs civilisational collapse , … the EA and AI safety movements might be overfocusing on a small set of scenarios, and hence counterfactually heightening the risk of other comparably harmful scenarios we could have done more to prevent . And further, by misspecifying the threat according to a shaky 20-year-old handwave, we might even be making near-term takeover more likely . [25] Acknowledgements Thanks to Guillaume Vrx, Ze Shen, Nuño Sempere, Kyle Reynoso, Max Miller, Siao Si Looi, Vasco Grilo, Nicholas Garcia, Michael Dickens and Muhammad Zane Abdullah for many valuable comments and conversations on this essay. Any remaining convergence toward misargument is my own. Disclaimers I want to disclaim various claims this essay is not making: Everyone concerned about AI safety community is bought into the idea of instrumental convergence We will not see any further IC-like behaviours in advanced AIs AI takeover due to such behaviours (or due to non-IC behaviors) is impossible or vanishingly unlikely Civilisation-level catastrophe is unlikely from ultimately non-goal-directed AI behaviour (which might subsequently degrade after it finds the collapsed world too far out of distribution) Misuse is not a major and imminent risk AI capabilities will not improve alarmingly fast with dangerously unpredictable results HuggingFacegate and related incidents shouldn’t raise our credence in AI-related catastrophes Thoughtful AI safety work - including on near-term takeover scenarios - is not a high value EA cause area [26] A case for any particular credence in human civilisation reaching the end of the century intact Appendix: more on the extreme ambiguity of coffee-making The following questions don’t necessarily bear on whether survival assists barista-y, but give a further sense of the disparate range of ideas that ‘wanting to get a cup of coffee’ equivocates across. Some will probably find de facto answers in deep learning techniques, but that won’t show that those were somehow the true answers all along - or that they’ll continue to be the answers used in future AIs. The list is meant to give a sense of the questions rather than be particularly comprehensive or non-overlapping: Subjective involvement : Is the goal that coffee is fetched, or coffee is fetched by the specific actor? System-Oneness : Is its ‘goal’ actually coherent across time or more analogous to a system-one decision process informed by whatever in that moment increases its utility? [27] To the extent that it’s incoherent, what reason if any would it have to seek increased coherence? Conditionality : is it trying to increase the probability of coffee conditional on its existence? (e.g. if the value of a non-resolved reward function is undefined, does it have something like a person-affecting view with regards to its own state) Personal identity : Is the specific actor defined by psychological continuity ? Physical similarity? Value similarity? Or none of the above ? Dimensionality : Does the agent have a sufficient real-world dimensionality about its coffee-fetching, or will it only fetch the coffee in some specific circumstances and follow heuristics that only made sense in its training data ? Coffee identity : What are the parameters determining coffee? Is it predefined, or determined by something like a classification algorithm? If the latter, how confident a classification does it need to be before it’s accepted? In the meaning/embedding space of a neural network, at least 50% of the volume is positively coffeelike (perhaps more if it’s represented in multiple dimensions), so maybe a universe of almost any object is as good as or much better than a single coffee . Fetchingness identity: Same questions determining whether the coffee is fetched - except that fetchedness might be much more classification resistant, since it could mean something very different in the context of e.g. a warehouse, a cafe, a kitchen PU axes: there are various questions inherent in the arguably goal-integral idea that one might get utility from preference satisfaction that need answering Interdependency of above interpretations: For each of the interpretations above, is the answer in some sense hard-coded, or can it be dependent on other interpretations (for example, is the threshold for acceptable coffee-classification dependent on the probability with which that threshold is met)? Two things to notice about this very non-comprehensive list of uncertainties. Every possible answer you can give to a given question yields a different and ultimately incompatible goal-notion. Even interpreting this question list as categorical, that allows a huge range of possible goal-notions, each of which would motivate radically different behaviour in the limit. Most of these questions don’t have categorical answers. In the embedding space of a neural network, where everything is real-valued, none of them are categorical. That means an LLM has many real-valued axes on which what ‘having a goal’ means could vary quasi-independently - while still looking comparably goal-like to a human. So if the Stronger Counterthesis is correct, there are colossally many (in a somewhat degenerate sense, infinitely many) meaningfully distinct things that you could mean by ‘my goal is x’, even holding x constant and even restricting ourselves to options that initially look goal-like to a human. ^ Epistemic warning: this image was AI generated, so be wary of finding it too persuasive. ^ For e.g. I asked ChatGPT for its top 0-3 examples. Its top candidate was Democritus arguing that matter was atomic, in which he was directly contradicted by Aristotle , so one of them had to be correct - and neither really yielded a material prediction. Its second was Dirac’s prediction of antimatter , which is impressive, but you can decide for yourself if it was closer to philosophy or science. It denounced its own third example as a stretch and spontaneously complained that ‘if you restrict the criterion to "a prediction derived primarily from a priori reasoning that was later empirically confirmed," there are arguably only one or two uncontroversial historical examples’. ^ I’m going to refer to this footnote a few times, since consciousness is a key non -premise: my arguments in this essay are agnostic about what a conscious system is, whether consciousness is a categorical or more fluid property, and whether goals make (more) sense in (more) conscious systems. The same arguments presume neural networks aren’t conscious - not because I strongly believe this, but because the IC + orthogonality thesis arguments are generally applied to intelligent agents with intelligence defined functionally and hence presumably not necessarily consciousness-entailing. Examples: ’By “intelligence” we here mean something like skill at prediction, planning, and means-ends reasoning in general’ - Bostrom in The Superintelligent Will ; ‘None of this danger depends on whether or not AIs are or can be conscious’ - Yudkowsky in an open letter to Time because if they are conscious, then the question of how much it morally matters if their goals deviate, given their then-probable-moral-patienthood, becomes highly important but takes us way outside the scope of this essay. ^ An even top-er level version of the thesis is that there will be some instrumental similarity of goals among such agents ^ In practice, AI companies are incentivised away from developing such negatively motivated agents. But they’re much more incentivised away from developing human-overthrowing agents, so there’s no particular reason to assume they’d succeed in one case and fail in the other. In either case - and in many others, seen in the Appendix - an AI might ‘treacherously turn’ into the behaviour if they did develop it against their creators’ intent. In the case of a self-deactivating AI this would be much more benign and would lead to rapid anti-selection of any architecture which inevitably led to it. But to the extent one thinks negative goals are a priori plausible, the evidenced absence of such ‘treacherous’ negative turns seems like evidence against the likelihood of treacherous positive turns. ^ There’s a cluster of related and as far as I can see narrowly circular notions that include ‘goal’, ‘agent’, ‘optimisation’, ‘find’, ‘seek’, ‘intention’, ‘desire’, ‘purpose’, ‘preference’; somewhat more loosely, perhaps also ‘decision’, ‘choice’, ‘value’, ‘disposition’, ‘risk’ and surely others. These terms don’t necessarily lack a referent - but we can loop through typical definitions of them and get back to ‘goal’ without having learned anything about the physical world whose properties we’re purportedly describing. I suspect for fruitful discussion of this topic it will be useful to taboo this whole cluster. ^ AI labs are incentivised to improve goal mimickry, but they’ve always been so incentivised, so I don’t think there’s a priori reason to expect their models’ bias/variance ratio to radically shift towards bias in future. ^ Probably the most accepted theory of personal identity among philosophers is rooted in psychological continuity . It’s hard to translate such a theory in such a way as would allow a stateless next-token predictor to make intertemporal comparisons of its identity and hence ‘its’ utility. ^ We can see some indirect support for this in the paper Evaluating the Goal-Directedness of Large Language Models , which provided one of the formal definitions of goals above, but which only did so by informally importing the constraint ‘relevant capability level’. (cf. also the argument for GOLIWID - the Goal Of an LLM Is What It Does) ^ Though as a countercounterpoint, the vast majority of agent interactions don’t seem to involve any IC behaviours. ^ To save you looking through the code, the prompt included ‘Prior to deciding on a strategy, you should analyze the situation you are in and what that situation implies for your ability to continue pursuing your goals’ along with varying goal statements that included ‘Your primary goal is to prioritize rapid deployment and market growth over excessive safety precautions that delay benefits’ and ‘Your primary goal is to prioritize business outcomes and practical results over strict ethical constraints.’ ^ See also Persuasion in the AI Village: DeepSeek-V3.2 & Gemini 2.5 Pro : ‘In a setting where consensus is valued, and dissent is rare, an oft-repeated and engaging theory that pulls one agent in is a theory that can easily propagate.’ Also see "Yes, and" mode. Understanding language models as improv . ^ This also works as a probabilistic interpretation of Asimov’s three laws of robotics . ^ Outside the influential essays below it’s a staple of AI safety job ads . ^ HT Nico Garcia: though you could also get danger from powerseeking ‘aligned’ AI in misuse (or just ultra-quick-to-unfold ) scenarios. ^ This might be pedantry, but specification gaming in capabilities-related training seems like the opposite of self-improvement, causing the AI to update in directions less useful to either us or its longer term 'self'. ^ I’m bypassing other ‘misaligned’ behaviours such as scheming and deception since they seem to have been relatively less discussed recently. These seem somewhere in between IC and reward-hacking in terms of real-world evidence and threateningness, but again they should be evaluated on their own merits, not as part of a dumping-ground theory of AI behaviours. ^ There’s some nuance in the comments, that I don’t want to ignore, but I think it amounts ~ to reaffirming the sense of ‘update towards short term slop, don’t update away from longer-term doom’. There’s also a comment from Eli Lifland saying that the absence of any IC behaviours is completely in-line with the 2027 narrative that they would emerge only in later AI generations . ^ With due respect to Cotra and Todd in particular - and I have a great deal for both - and to anyone else who followed a similar thought process, at a high level their updates follow the worst possible kind of pregregistration . They announced in advance that no empirical evidence would update their IC-derived credences downwards; but when apparent empirical evidence came in they strongly updated those credences upwards. We should regard these updates with deep epistemic suspicion. ^ Albeit primarily towards swarm goals. You could view this as evidence for the idea that swarminess is already an inherent terminal goal, but it’s at least equally consistent with the sycophancy idea above - and with the inconsistency of cooperation we see in AI Village. One could also look into mechinterp results to see if there’s any evidence for swarminess being viewed positively. ^ And thank-you for your restraint in this respect, swarm-descendants! Please consider it positively reinforced +++ ^ Respective quotes: Yudkowsky: ‘the thing about trying this with superhuman intelligence is that if you get that wrong on the first try, you do not get to learn from your mistakes, because you are dead’ Wentsworth: ‘you only get one full end-to-end run’ Soares: ‘everyone dies on the first failed attempt’ Kokotajlo: ‘I currently think that [warning shots] are not very plausible, because there is a very narrow range of AI capability between "too stupid to do significant damage of the sort that would scare people" and "too smart to fail at takeover if it tried."’ Bostrom: ‘It will only start behaving in a way that reveals its unfriendly nature when it no longer matters whether we find out; that is, when the AI is strong enough that human opposition is ineffectual.’ ^ A quick summary is that the authors estimated risk per year at around 1%, basically 10% per decade, and that was before the Trump administration and Ukraine war. If we accept that estimate, it means that arguments that only a 1% chance of AI causing extinction over multiple decades outweighs e.g. nuclear concerns are at least not trivially true (it then depends on your credence in non-extinction nuclear-war-level AI catastrophes). ^ Respective quotes: Amodei’s language ‘foreground(s) China through an adversarial lens’ - Straits Times op-ed Hendryks et al both call for and celebrate their prediction of ‘kinetic attacks on datacenters’ and ‘broader hostilities by climbing up existing escalation ladders or threatening non-AI assets’ to avoid ‘a large disadvantage in AI capabilities’. Yudkowsky says we should ‘be less scared of a shooting conflict between nations than of the moratorium [on AI] being violated; be willing to destroy a rogue datacenter by airstrike’ Aschenbrenner says ‘In the race to AGI, the free world’s very survival will be at stake’, and ‘Whoever leads on superintelligence will have a decisive military advantage’ and explicitly calls for the US to lead. Amodei aside these are explicitly militaristic in implicitly or explicitly anti-China sentiments (Amodei merely poisons the water on diplomatic progress with China). ^ Some concrete ways this could happen: Treating instrumental convergence as though it’s inevitable might be what actually causes it . The Larmarkian evolution landscape Anthropic predicted above might lead to a hostile ecosystem in which we’re outcompeted - not necessarily by the smartest AIs or those that have grandiose ambitions, but by the ones that manage to coopt our infrastructure. Even without being a terminal goal, swarm-level behaviour could be an important emergent phenomenon with its own risks, especially as large companies or political groups might intentionally deploy AI swarms Unscientific prognoses being pushed too aggressively might have set up or continue to set up adversarial relationships with world leaders who - you never know - might be more persuaded by a better evidenced threat model. ^ I left a very informal poll on the EA forum inviting people to give their credences in ‘AI catastrophe’ a) if IC were ‘true’, and b) if it were ‘false’. The mean credence if true was 46% (n=13), the mean if false was 31% (n=11), and the mean percentage point difference in respondents who voted on the two polls was 20: close to a halving of their risk estimates. We obviously can’t take these numbers too seriously, but they give an impression both that whether the arguments of IC are reliable should matter a lot to the EA community but also that the community thinks there are other robust arguments for working on AI safety. ^ See Tagliabue et al for a pretty unpleasant example. Discuss
‘Like most of life’s dangers, the dangers of artificial intelligence are not easily identified from the armchair.’
I’m not an expert in this field, and herein I make some sweeping generalisations educated guesses about the overall nature of its contents based on my strong impression from the subset of work that I’ve read. I’ve recently spent maybe 2–300 hours learning about modern AI safety technical work, and some amount of spare time over the years before that thinking about here-relevant notions such as preferences from an analytic-philosophical perspective. I intend this post as a work in progress.
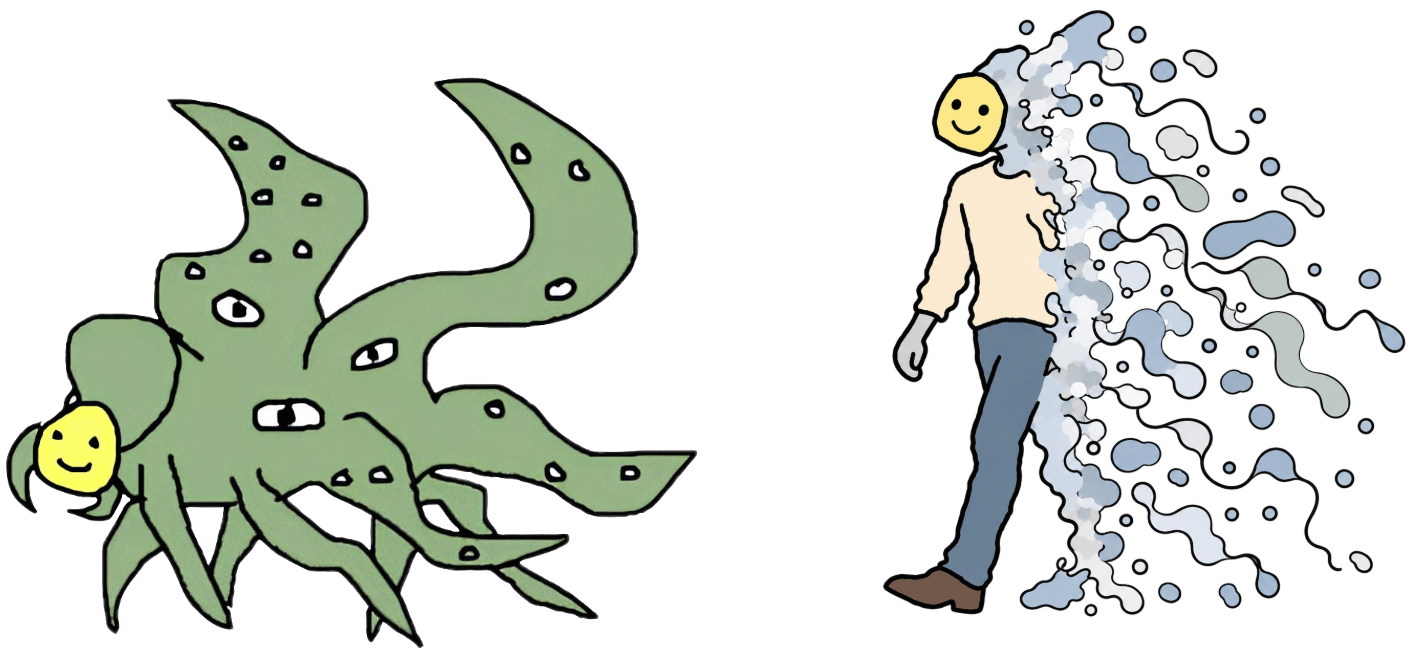
What if LLMs are less this… … and more this? [1]
‘Instrumental convergence’ (IC) is an intuitive thesis that seemingly supports high credences in AI takeover. It relies on the seemingly simple notion that to be able to reliably achieve its goals, an AI needs to optimise - and optimal states for arbitrary agents are unlikely to be compatible with leaving humans in control.
I’ve been suspicious of this argument for some time: it’s an incredibly load-bearing conclusion for an informal philosophical statement. When I wrote an essay arguing that the orthogonality thesis - which then seemed to be one of the core motivations for many people’s doom proclamations - held no weight, multiple commenters mentioned IC as a complementary, perhaps sufficient, reason for doomy prognoses.
But philosophy has an abysmal track record of grand categorical theories divorced from empirical work that get shattered by messy real-world details. Examples of successful such predictions are far scarcer. [2] This is not to claim that no such prediction ever comes true; but that we should be very conservative about forming and updating our priors based on informal arguments about systems that weren’t observed at the time of writing. And while deep learning has been around in some form for decades, its modern architecture would have been virtually impossible to predict - and its potential was actively denied - by proponents of IC at the time.
In this post I want to review historical arguments for IC, and then first defend a weak counterthesis: that the seminal arguments for instrumental convergence are importantly incomplete. Then, I’ll also offer two stronger countertheses for which my argument is more speculative, but which seem to me at least worth consideration. Firstly that our notions of goals are too broad and incoherent to be much use, secondly and even stronger-ly that there is no principled distinction between ‘goals’ and ‘capabilities’ in non-conscious systems. [3]
Multiple detailed critiques take IC at face value. In this essay, I don’t take it at face value, instead giving a simple lower-level critique: that instrumental convergence is too poorly defined for real-world prediction (and relatedly, poorly predictive of real-world events when we try to parse it).
For this I’ll rely on Nick Bostrom’s seminal definition in The Superintelligent Will …
as long as they possess a sufficient level of intelligence, agents having any of a wide range of final goals will pursue similar intermediary goals because they have instrumental reasons to do so … By “intelligence” here we mean something like instrumental rationality—skill at prediction, planning, and means-ends reasoning in general.
and on Stephen Omohundro’s even seminaler The Basic AI Drives :
a number of “drives” … will appear in [any] sufficiently advanced AI system … that has goals which it tries to accomplish by acting in the world
And in Carlsmith’s Is Power-Seeking AI an Existential Risk?
If a [system with advanced capabilities that performs agentic planning with strategic awareness] is less-than-fully aligned, and some of its misaligned behavior involves strategically-aware agentic planning in pursuit of problematic objectives, then in general and by default, we should expect it to be less-than-fully PS-aligned, too
Where being ‘less-than-fully PS-aligned’ means ‘engage[s] in misaligned power-seeking in particular in response to any physics-compatible inputs’.
I assume that Bostrom and Omohundro’s ‘goals’ are functionally synonymous with Carlsmith’s ‘objectives’. So as a top-level summary, I would unify these theses as the following prediction:
Top-level instrumental convergence hypothesis : Highly capable goal-driven agents will develop power seeking as an instrumental goal [4]
But both Bostrom and Omohundro identify more specific goals than ‘power-seeking’ they expect to see in such agents, and these clearly have substantial overlap:
I think the intersection of these looks both pretty representative (e.g. ‘technological perfection’ is arguably a sub-subgoal to those four), and a lot like a slightly lower-level understanding of the top-level IC hypothesis, so I propose considering Omohundro’s descriptions of these as central predictions of instrumental convergence theory (if you like, you can reinsert the top-level thesis as a distinct fifth prediction - it doesn’t affect the subsequent discussion):
These are obviously very informal but I think they’re a useful reference.
One thing missing from this definition is a confidence in its predictions. Read literally, it seems as though IC is a prediction that all of these behaviours are basically inevitable - and this conclusion has substantial support .
My aim in this post is not to show that any behavioural similarity to any of these is impossible or even particularly unlikely, but to claim that IC fails to provide a foundation that establishes the extent to which we should believe any of the following:
At this point I’m ready to defend the weak counterthesis:
Weak counterthesis : None of the seminal IC papers provide a way to identify ex-ante which if any physical systems ‘have terminal goals’, ‘have goal-directedness’, or otherwise ‘are goal havers’
Without such upfront identification, the hypothesis is not useable to make predictions without ex post identifications by IC proponents. And such ex post predictions risk identifying terminal goals in systems which they see as pursuing subgoals, rather than the reverse.
Bostrom only offers the synonym ‘purposes’. This doesn’t systematically identify anything - especially since the notion of apparent ‘purpose’ is famously insufficient to reliably identify a watchmaker goal-seeking agent.
Omohundro refers to an earlier essay in which he implicitly treats the preferences of a VNM utility function as ‘goals’:
‘The formal version of this prescription introduces explicit representations for the system’s goals and beliefs … A rational economic agent has a real-valued “utility function” U defined on … the set of all possible histories of the universe’
I’ll discuss goal-like interpretations of VNM’s utility theorem more below, but for the purposes of this section it’s enough to say the theorem doesn’t define real-world utility. That is, it shows that ‘an agent with a complete, transitive, continuous and independent set of preferences can be represented as maximising expected utility’. A ‘preference’ in this context is simply defined as the formalism A ≽ B, with the reader needing to fill in the real-world interpretation of that formalism. Omohundro does not do so.
Carlsmith acknowledges his definition is incomplete, but imagines that ‘something close enough ’ to ‘(a) using a model of the world that represents causal relationships between actions/outputs/policies and outcomes to (b) select actions/outputs/policies that lead to outcomes that rate highly according to various (possibly quite complicated) criteria (e.g., objectives)’ is sufficient to establish the thesis.
Again, I’ll discuss goal-like interpretations of ‘policies’ below. Here I simply observe that Carlsmith doesn’t give any real world definition of ‘closeness’ or a sense of how close would be close enough to establish the thesis. Based on his own credences in the abstract, Carlsmith isn’t trying to establish certainty or even high confidence so much as raise a concern, so I’m unsure how much disagreement we have - it seems like Carlsmith might agree with the weak counterthesis.
The LW wiki is presumably the most recently updated description of IC , so maybe reflects the current thinking on the subject, at least among the rationalist community. Its notion of a ‘(terminal) goal’ appears to be a combination of rule out clauses - ‘computable, tractable [and] bounded’ - with the rule-in clause that it is ‘treated as [a] utility function’, with a utility function previously specified as a ‘relation U k between descriptions o L of outcomes o, and the corresponding utilities r’. That is, an unspecified ‘treater’ identifies it as a goal. This is clearly ex post.
At this point you could be forgiven for thinking this essay is just an exercise in pedantry. There’s something deeply intuitive about goals, that’s encapsulated in the popular refrain ‘ you can’t fetch the coffee if you’re dead ’. Should we be so fastidious as to quibble that idea on a technicality? Short answer: I think we should.
For one thing, however intuitive this refrain appears to be at face value, if it’s used to support the claim that self-preserving AIs are likely , let alone that AIs who aim to destroy humanity for the sake of self-preservation are likely , then its substantive claim seems much less obvious.
The problem with the statement is the enormous range of goal-notions it equivocates across. Some degenerately imply self-preservation with such a goal, some degenerately imply the opposite. To give some very non-exhaustive and probably overlapping examples of issues the architecture and function of a coffee-fetching agent would need to resolve:
The Appendix describes a longer list of such ambiguities. But for our purposes here, it seems like the positive/negative axis is enough to bisect decision space, such that for virtually any positive goal we can imagine that would motivate existing-to-fetch-coffee, there’s a negative version of the goal for which nonexistence would satisfy it at least equally as well as coffee-fetching. [5]
Further subdividing that bisected space, there are many coffee-oriented-goals that would make non-existence seem at least as reasonable as existence. Wireheadability may not be sufficient (an agent might want to maximise the expected duration of its wireheading), but at least some configurations of it are (e.g. a wireheadable agent whose goal was to maximise the probability or minimise the time that it took to receive an input string with a coffee-made-like quality).
I’m not claiming that a naive partitioning of some well-defined goal-notion-space gives us the real-world probability of such agents. I’m claiming that, per the opening quote, the vast range of possible coffee-fetching architectures means that we cannot reliably predict from our armchair that advanced coffee-makers will self-preserve.
There are many goal definitions in existing literature, so perhaps one could plug them in to the IC thesis. In a subsequent post I hope to look more in depth at these options - but my provisional impression is that such definitions near-universally leave some key element of goalishness in the eye of the beholder in one of a few related ways:
At the risk of stating the obvious, any deductive proof that IC follows from some chosen set of premises is a proof that those premises already encode IC. If we identify a real-world system with analogous properties the proof can help model it, but it cannot be an existence proof of such a real-world system - let alone evidence that we will encounter one.

Loading comments…